Best AI This Month? Prediction Market Prices & Outlook
Google, Anthropic, OpenAI, and Meta are competing for the top spot in October's AI rankings. Here's how prediction market traders are pricing the race.
Google's Gemini has emerged as the clear favorite in Kalshi's October AI prediction market, with Anthropic's Claude its closest challenger. Meanwhile, new model releases from OpenAI and Meta are adding another dimension to the competition.
The market will ultimately be decided by the LM Arena leaderboard on October 31. Measurable model rankings are the determining factor for resolution, not popularity, adoption, or which AI chatbot has the most users.
Market Snapshot
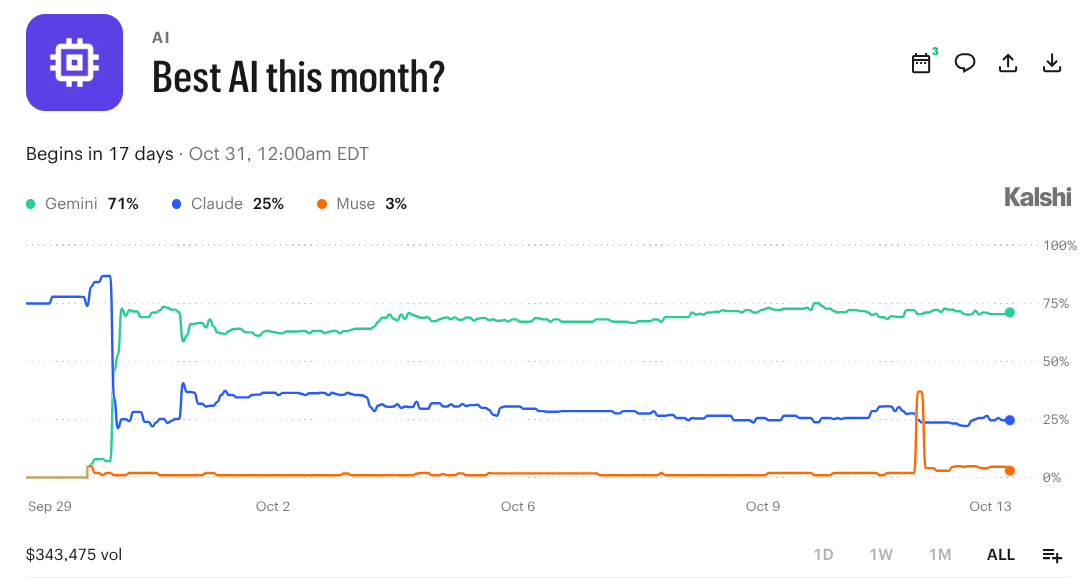
The market is heavily concentrated around Google and Anthropic. Gemini commands a substantial lead, while Claude is the only other contender trading above single digits.
The disparity is particularly notable given the intensity of competition among leading AI developers. Traders are not treating the field as an evenly matched contest, even with more than two weeks remaining before the ranking is finalized.
Why Gemini Leads the October AI Race
Google's position is supported by the latest available LM Arena Text leaderboard, which ranks AI models using human preferences from blind comparisons.
On LM Arena's October 8 overall Text leaderboard, Google's Gemini 4 Argon ranked first with a score of 1,525, ahead of Anthropic's Claude Opus 5.5 at 1,507. Gemini's score was marked preliminary, with fewer than 5,000 votes recorded, leaving room for its ranking to change as additional evaluations accumulate.
The leaderboard also helps explain why Kalshi traders favor Gemini without treating the outcome as settled. Gemini's score was still classified as preliminary, meaning additional evaluations could affect its standing before October 31.
Claude's position is particularly relevant. Anthropic does not need to overtake Google across every benchmark or product category. It only needs one qualifying model to finish above Google's best entry under the market's resolution criteria.
Meta's New Models Add a Wildcard
Meta introduced Muse Wonder and Muse Wonder Full on October 12, bringing another significant release into the competition just weeks before the deadline.
The company describes the models as its most capable yet, emphasizing complex agentic tasks, memory, and sustained problem-solving. Independent coverage has highlighted the advances while noting that some performance comparisons rely on Meta's own testing.
Meta already had Muse Spark models represented on the leaderboard, but the October 8 snapshot predates the Wonder announcement. Until the new models establish their standing in the relevant rankings, their effect on the October contract remains uncertain.
What About ChatGPT and the Other Contenders?
OpenAI's October 7 GPT-6 announcement introduced new capabilities and an interactive interface for ChatGPT. But Kalshi's contract is determined by LM Arena rankings, not product features or commercial adoption.
The distinction is that new features and product improvements do not necessarily translate into a higher LM Arena position. OpenAI remains a major AI developer, but the October market measures a specific competitive result rather than the broader success of ChatGPT.
Alibaba's Qwen, Moonshot's Kimi, and xAI's Grok are each priced below 1%. Their low probabilities reflect limited trader expectations of a first-place finish, not an absence of capabilities or usefulness in particular applications.
How Will Kalshi Determine the Winner?
The contract resolves according to which company's large language model holds the top position on the LM Arena leaderboard on October 31.
If models are tied under Rank (UB), the higher Arena Score determines the winner. Further ties are settled by vote count and then release date.
That makes the final leaderboard, not a company's announcement, independent review, or performance on an unrelated benchmark, the decisive result.
The Bottom Line
Google enters the final weeks of October with both a substantial prediction market advantage and the leading position in the relevant AI rankings. Anthropic remains its most credible challenger, while Meta's newly released models introduce an additional variable.
The next development worth watching is how the leaderboard responds as more evaluations arrive, particularly for recently released models. With settlement approaching, even a relatively small change at the top could reshape market expectations.
For a broader look at how these contracts work, see our complete guide to prediction markets.